8 minNovember 20, 2026

Our tools monitor millions of native, push, pop, and TikTok advertising campaigns.
Get StartedFor the last decade, “composable” has meant swapping SaaS components in and out of a martech stack. APIs made it possible to deconstruct monolithic suites into interoperable services, letting teams replace a CMS or add a personalization engine without rebuilding everything, as one overview of how AI is pushing composability beyond software points out.
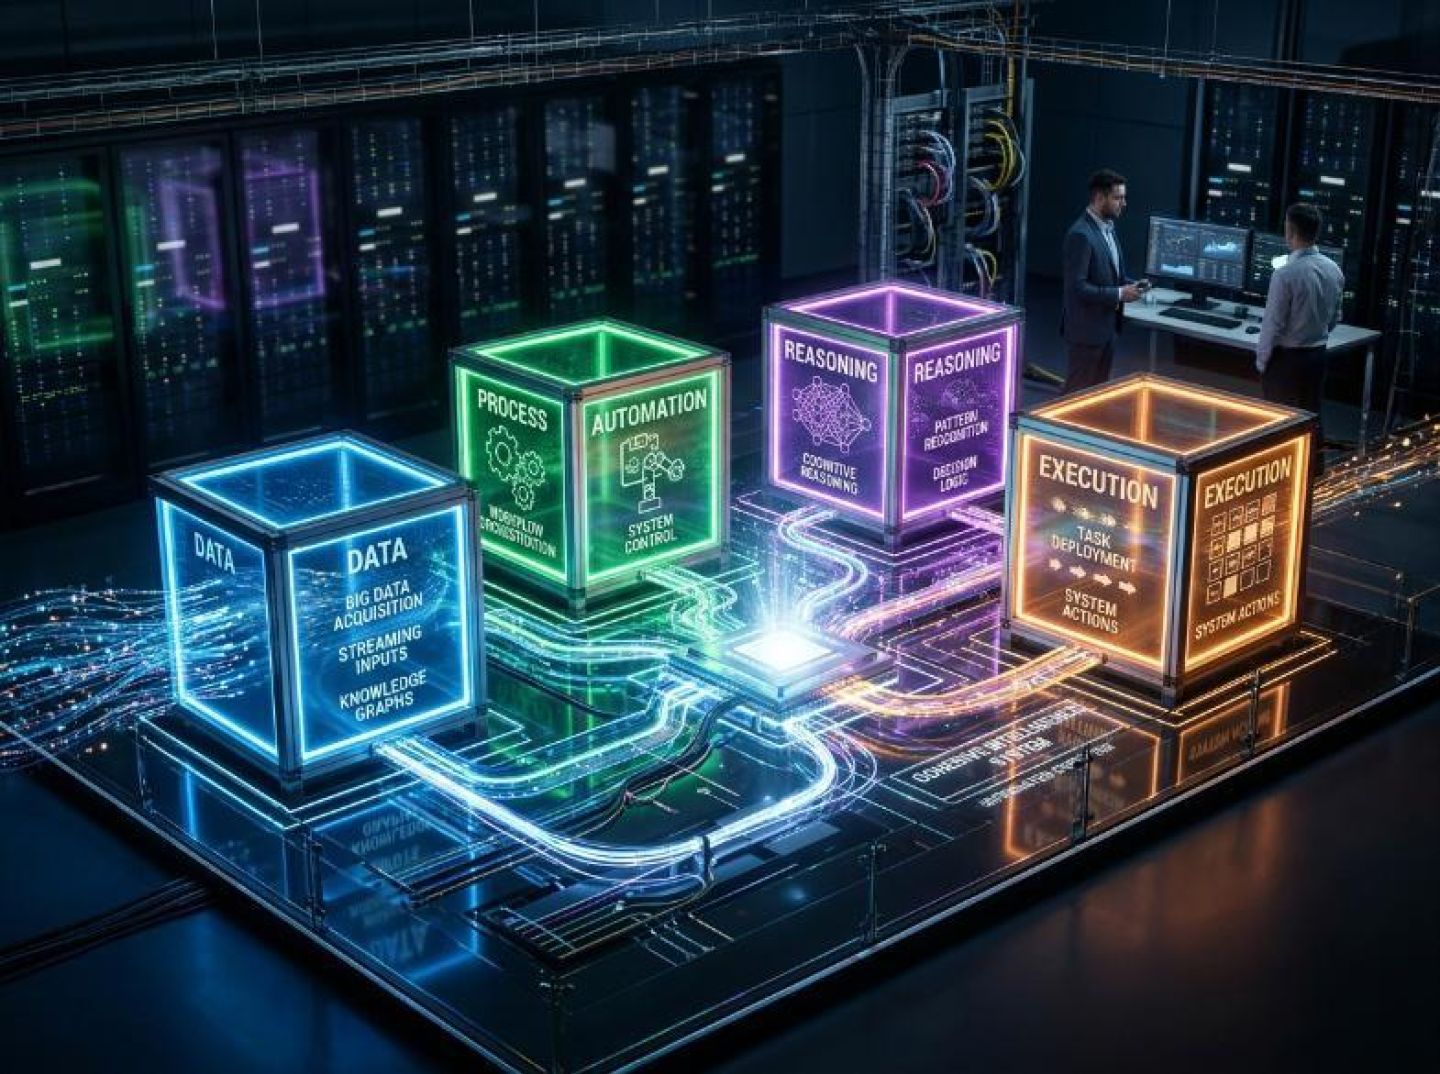
But that was composable software. What is emerging now is composable intelligence: modular agents that can reason, plan, and act across those systems. That shift is exactly why agent stacks are becoming as important as traditional martech architecture.
You can already see this in how advertising tools are normalizing multi-agent orchestration. AdStellar AI, for example, presents its Meta campaign-building capabilities as an “orchestra” of specialized agents that analyze pages, structure campaigns, allocate budgets, and surface results in a dashboard, according to the HubSpot Marketing Blog’s review of campaign optimization platforms.
The user does not necessarily think, “I am managing seven agents.” They think, “I am launching better campaigns faster.” But underneath, that is a composable intelligence stack: discrete specialists, each with a defined responsibility, working together to deliver a larger capability.
The major advertising platforms are moving in a similar direction, although at ecosystem scale. TikTok is developing agentic experiences for lead qualification, conversational shopping, search campaigns, and creative selection. Meta is also expanding its AI-powered business assistance and natural-language campaign tools. These developments are part of a broader shift toward agentic capabilities across advertising and commerce.
What looks like more automation is actually an emerging architectural pattern: layered agents attached to different parts of the customer journey and coordinated, at least for now, by human operators.
Inside marketing organizations, this pattern is forcing a structural rethink. Marketing operations teams are no longer just managing software. They are beginning to manage fleets of agents.
Instead of manually building every workflow, teams define what agents are allowed to do, where they get their data, which APIs they can access, and when a human must review their work. A recent analysis of how marketing operations is restructuring around autonomous AI agents explores this transition.
Some organizations are even establishing centralized AgentOps or agent-factory groups to build, test, and certify reusable agents against brand, security, and privacy standards before deploying them across teams.
That shift aligns with a broader architectural trend. The martech universe contains thousands of products, yet it is increasingly practical to build specialized automations and AI workers on top of open platforms. Emerging protocols such as MCP are also creating new ways for agents to connect with tools and data, extending the idea of composability beyond traditional software integrations.
Instead of composing only software capabilities, advanced teams are beginning to compose decision-making and execution itself.
At the same time, the industry's expectations remain pragmatic. A recent IAB Europe survey summarized by VideoWeek found that operational efficiency remains a primary way organizations evaluate AI performance. Many agentic systems still operate at lower autonomy levels, with humans directing or monitoring important decisions.
That gap between what technology can potentially do and what organizations are prepared to trust is why agent stacks need to be intentionally designed.
Composable intelligence is not about replacing your martech stack. It is about layering an agent stack on top of it.
The winners in ad intelligence will not necessarily be the teams that bolt on a single AI assistant. They will be the teams that architect reusable, well-governed agent capabilities for competitive research, experimentation, and campaign scaling—capabilities that can be connected, upgraded, or replaced as their needs evolve.
Power users in ad intelligence live in a paradox: they have more data, more channels, and more automation than ever, yet their days are still defined by bottlenecks.
The problem is not necessarily a lack of dashboards or AI tools. It is that connecting everything together still depends heavily on human effort.
The job starts with relentless cross-network research. You are tracking what competitors are doing on Meta, YouTube, TikTok, LinkedIn, Reddit, programmatic video, and whichever new advertising surface appears next.
Each platform exposes its own partial view of the market. Meta's Ad Library tells one story, TikTok's Creative Center another, and YouTube placement data a third. Meanwhile, platforms are embedding their own AI assistants directly into their advertising environments.
TikTok's developing AI capabilities span conversational shopping, lead qualification, automated search campaigns, and creative selection, effectively creating more agent-mediated experiences across the advertising funnel.
Those native agents optimize within their own ecosystems. You, however, still need to understand what is happening across all of them.
That means spending hours reverse-engineering patterns that individual platforms may not reveal directly:
You are not just researching advertisements. You are researching systems: the relationship between audiences, formats, placements, offers, and creative strategies that no single platform interface can fully explain.
At the same time, creative velocity has become a survival requirement.
AI-native advertising rewards brands that can test continuously instead of thinking only in traditional campaign cycles. As one analysis of self-optimizing agents and AI-native advertising argues, performance increasingly depends on having a consistent stream of on-brand, on-message variations that can be adapted to different contexts.
Tools such as AdStellar AI illustrate this direction through coordinated agents designed to analyze pages, plan campaign structures, and support faster Meta campaign creation, as discussed in the HubSpot Marketing Blog's review of campaign optimization platforms.
But vertically integrated systems do not automatically solve the multi-network problem.
Your TikTok creative taxonomy may not match your Meta UGC pipeline. Your YouTube scripts may live in Google Docs, your Reddit concepts in Slack, and your creative briefs in Notion.
When every platform expects a steady flow of personalized video, native formats, and context-specific messaging, creative debt can compound faster than a human team can manage it.
Then there are the decision bottlenecks.
A recent survey of European advertisers found that operational efficiency remains a major measure of AI success, including faster reporting, more efficient optimization, and leaner media operations, according to VideoWeek's coverage of the research.
Yet many agentic implementations still operate within narrow, human-directed tasks.
Media teams continue to spend disproportionate time:
That last point matters.
As more platforms introduce self-driving campaign types and conversational setup flows, advertising specialists are being pushed upstream into governance and strategy. Their responsibility is increasingly to define which outcomes matter, which trade-offs are acceptable, and where automation must stop.
As one overview of AI-native advertising operations and governance explains, the real work is shifting away from simply pressing buttons and toward setting boundaries and supplying the right strategic inputs.
Power users are not short on AI. They are short on connective tissue.
Native agents optimize within walled gardens. Creative tools accelerate production for individual channels. Reporting copilots summarize what happened yesterday.
What is missing is a composable layer of agents that can research across networks, normalize patterns, translate insights into channel-specific tests, and enforce strategic constraints at scale.
The solution is not one enormous AI system. It is an orchestrated stack of specialized capabilities.
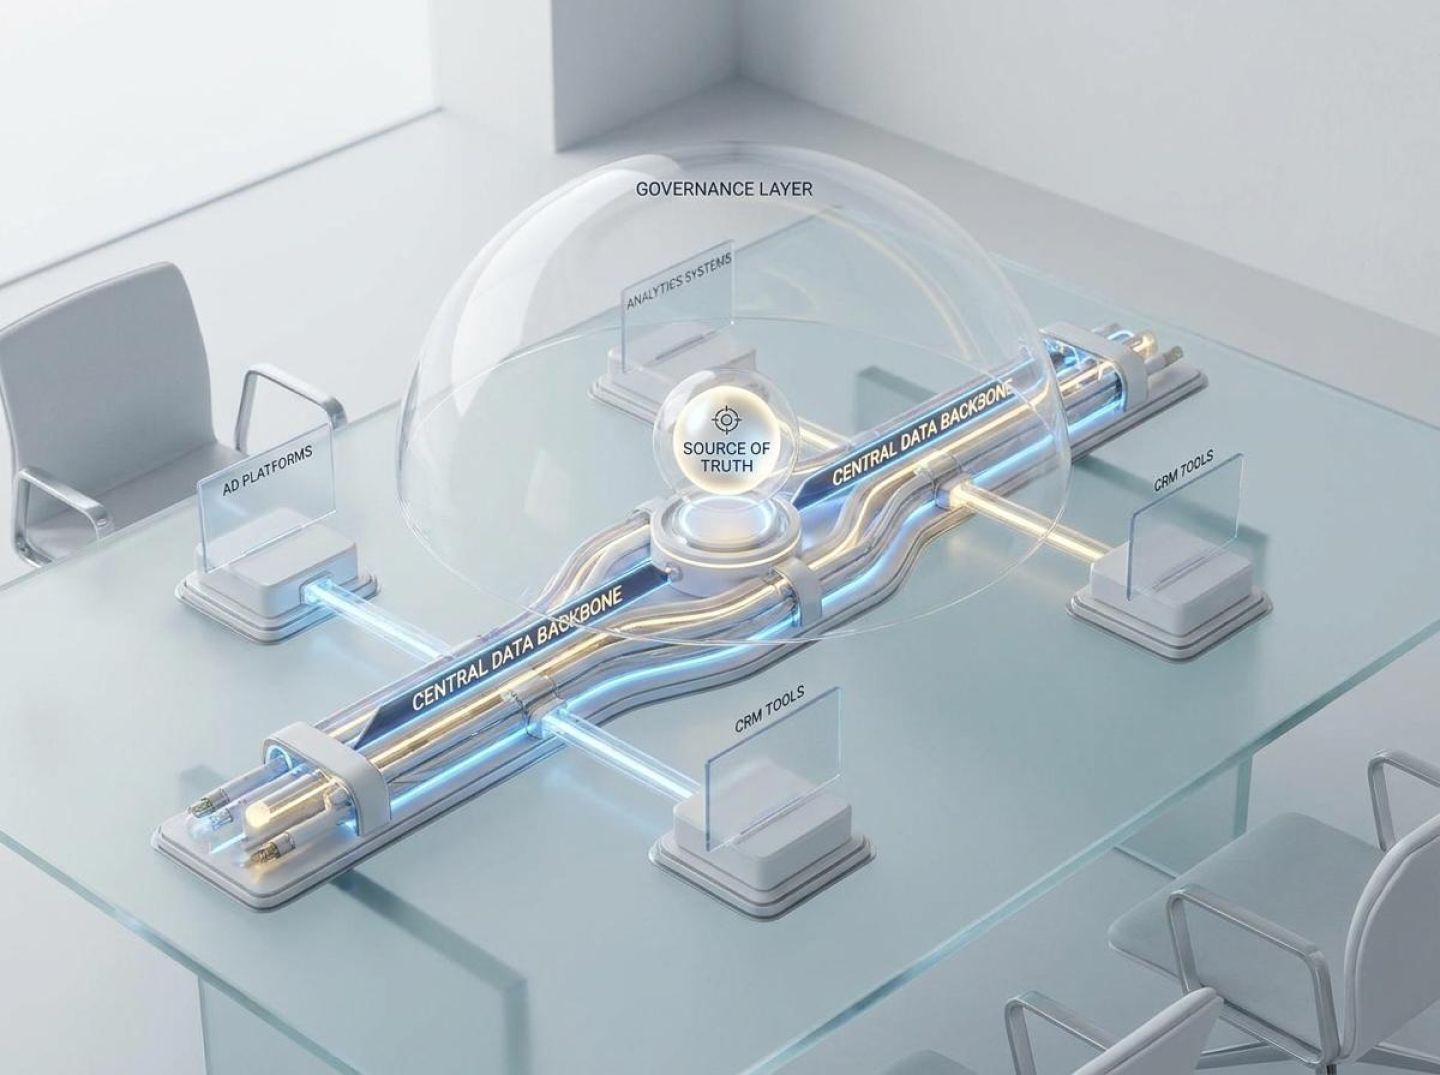
If your agents are the muscles of your ad-intelligence stack, the spine is everything they stand on: the data model, governance layer, and integrations that connect them to advertising platforms and analytics systems.
Get this wrong, and your orchestra of agents becomes a collection of disconnected tools. Get it right, and you can safely let agents research, test, and scale across networks without losing control of budgets or compliance.
Most teams are tempted to connect agents directly to individual platforms—Meta, TikTok, Reddit, and internal business intelligence systems—and let them figure out how everything fits together.
That is how brittle workflows and inconsistent decisions develop.
A better approach is to define a canonical advertising schema that includes:
Each entity should have identifiers and standardized fields that make it possible to compare information across channels.
This becomes the connective tissue your agents use to compare what competitors are running on TikTok with what is working for your own campaigns on Meta, without rebuilding the mapping logic for every task.
The data backbone should be supported by a centralized source of truth.
Before deploying agents, one marketing leader profiled in an article about improving marketing workflows with AI agents built a unified repository of brand tone, value propositions, product details, and competitive positioning so agents would not have to improvise from scratch.
For ad-intelligence power users, that same principle should extend to:
Your source of truth is not just a data repository. It is a record of the organization's accumulated judgment.
Governance is where that judgment becomes enforceable.
As agentic systems move closer to real-money decisions, trust becomes a major constraint. The IAB Tech Lab's AAMP 2.3 framework is one example of industry work focused on governance, privacy, and safeguards for AI agents operating within advertising systems, as discussed in MarTech's overview of the framework.
Even if your organization never adopts AAMP itself, the underlying principle is useful.
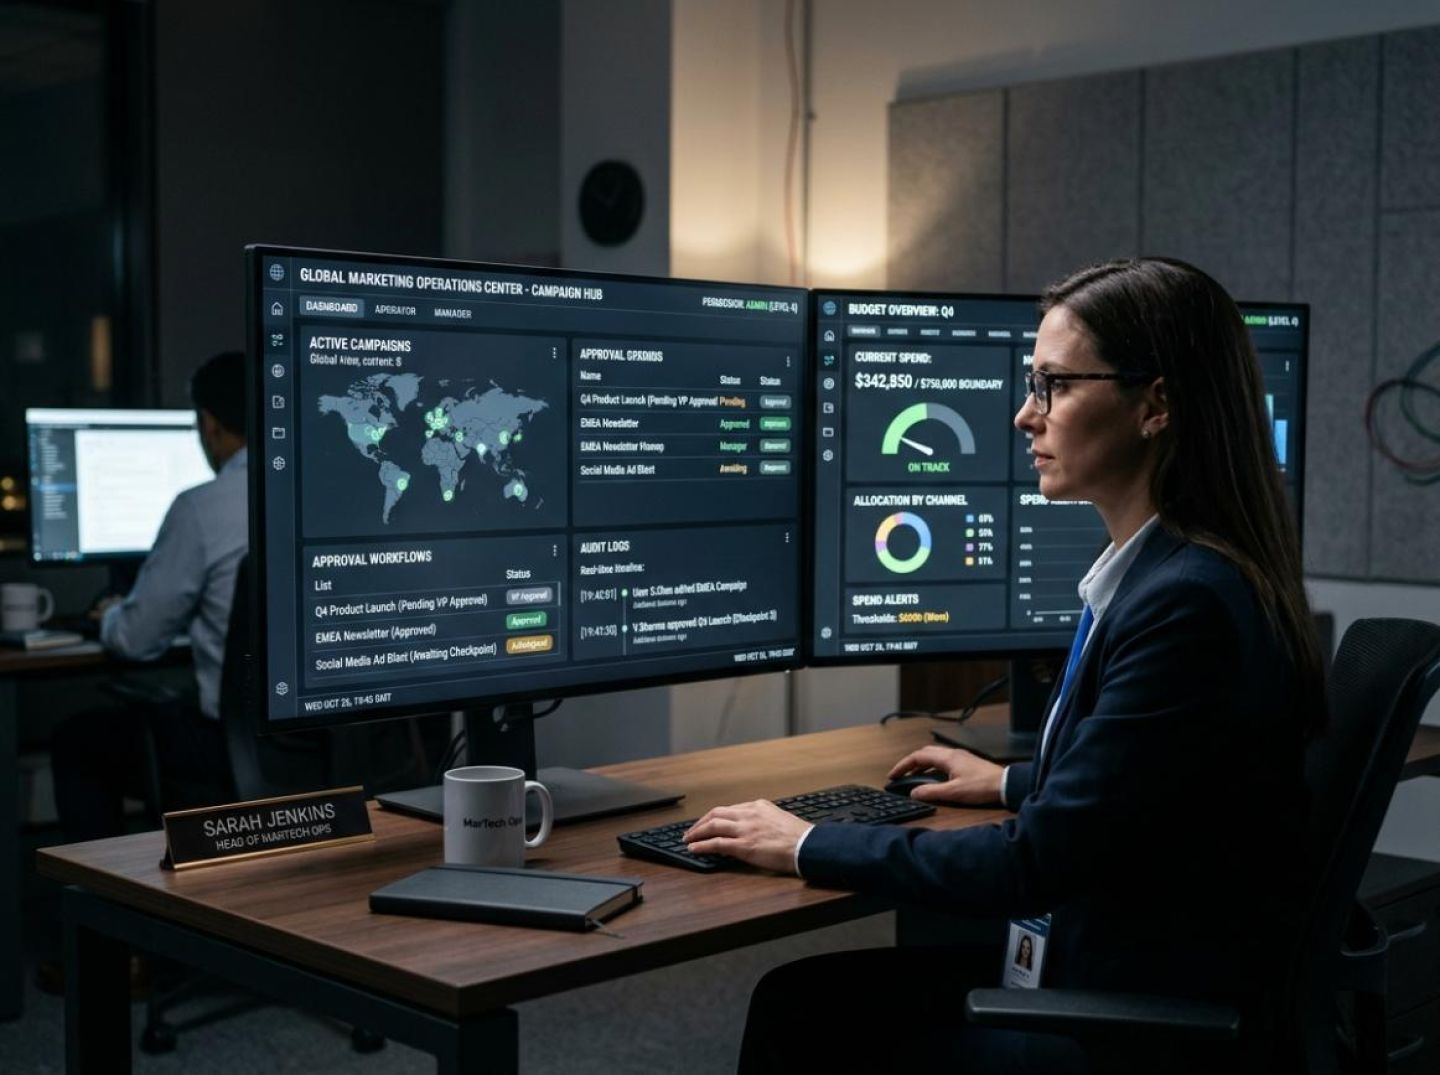
Define what agents may access, what decisions they may recommend, what actions they may execute, and which thresholds require human approval.
The industry-wide focus on operational efficiency also reinforces this approach. Research summarized by VideoWeek suggests that organizations continue to prioritize practical efficiency while retaining meaningful oversight.
Your governance layer should reflect that reality.
Automate repetitive work such as data collection, taxonomy normalization, routine reporting, and pre-approved bid adjustments. Reserve structural decisions—such as entering new markets, introducing new offers, or reallocating substantial budgets between channels—for human review until the system has earned sufficient trust.
On the integration front, think in terms of agent corridors rather than isolated point-to-point connections.
Your architecture needs at least three types of corridors.
1. Execution corridors
These connect agents to the platforms where advertising activity and spending take place.
Meta and TikTok are expanding their AI-powered advertising and commerce capabilities, from conversational campaign setup to lead generation and creative selection. These developments are covered in industry reporting on AI-driven campaign tools and agentic commerce.
Your architecture should standardize how agents authenticate, submit approved changes, and retrieve performance information from each ecosystem.
The goal is to add or replace a channel without rewriting the entire stack.
2. Insight corridors
These connect agents to analytics, CRM, and experimentation platforms.
If agents are expected to recommend experiments rather than simply produce reports, they need coherent feedback loops.
That means consistent user and account identifiers, clear mapping between impressions and downstream revenue, and integrations with the systems where experiments actually run.
Platforms such as AdStellar illustrate the value of connecting campaign configuration, creative variants, and performance insights around business KPIs such as ROAS and CPA, as discussed in the HubSpot campaign optimization overview.
3. Knowledge corridors
These connect agents to institutional memory.
A competitive-intelligence agent is only as useful as its ability to compare what changed this week with what the team has already observed.
A structured knowledge base can preserve competitor activity, ad-library observations, product announcements, landing-page changes, and previous experiment results.
This is consistent with the approach described in MarTech's discussion of foundational AI agents for marketing workflows.
The knowledge layer should be a first-class integration that agents can both read from and update—not merely a separate wiki that nobody maintains.
Designing this spine is unglamorous work, but it is what separates a clever demonstration from an operational advantage.
Agents can only be as composable as the data standards, governance rules, and integrations they are built on.
If the spine of your stack is data and integrations, the real leverage comes from the agents operating on top of it.
Think of these as modular roles on a performance team, not monolithic do-everything bots.
Each agent owns one job in the spying, testing, and scaling loop. You can then combine them into a larger system, much like composable martech stacks were assembled from APIs and microservices.
Here is a practical roster.
This agent handles competitive intelligence.
It collects publicly available advertising examples, landing-page information, and organic content from Meta, TikTok, Reddit, YouTube, and search platforms. It then normalizes those observations into the shared data model.
Beyond collecting ads, it identifies recurring patterns:
It can also monitor developments in advertising ecosystems, such as TikTok's agentic advertising tools and changes in lead-generation or commerce experiences.
The Spy Agent turns scattered observations into a structured view of what competitors are doing by network, category, and funnel stage.
Importantly, public advertising observations should not be treated as proof of actual performance. The agent records what is visible and distinguishes observed activity from inferred strategy or results.
Once the Spy Agent has collected patterns, another agent turns those observations into hypotheses.
The Message and Offer Synthesizer combines competitive angles, first-party performance data, and product constraints to propose testable narratives.
For example:
This agent does not launch campaigns.
It produces structured test ideas containing proposed hooks, offers, messaging angles, creative directions, and reasons for prioritization.
The objective is to turn raw intelligence into hypotheses that a team can evaluate and test, rather than treating competitor activity as a strategy to copy blindly.
The Creative Orchestrator coordinates the production process.
It works with specialized tools such as image generators, video editors, scriptwriters, and human creatives. It takes the Synthesizer's hypotheses and turns them into production-ready instructions.
Its responsibilities include:
Crucially, it also enforces the governance layer.
Brand guidelines, legal restrictions, required disclaimers, and platform policies should be applied before creative assets move into production or campaign setup.
More agents should mean more coordinated output, not more compliance risk.
This is the planning agent.
It determines which ideas should be tested, where they should run, and how success should be evaluated.
Using the constraints defined in the governance layer, it can:
For example, it might recommend testing a new offer across two creative formats while keeping the audience and landing page consistent.
That helps the team understand whether the results are associated with the creative change rather than several unrelated variables.
Most organizations are still using AI primarily for reporting and programmatic optimization rather than complete autonomous decision-making, as VideoWeek's coverage of IAB Europe research highlights.
This agent should therefore operate with limited autonomy. It can propose experiments and prepare their configurations, but humans retain approval rights over budgets, strategic changes, and risk.
Once an experiment has been approved, the Campaign Launcher handles the operational setup.
Its responsibilities include:
The agent should not independently rewrite the experiment's objectives or override its budget restrictions.
This is where operational efficiency becomes tangible. Repetitive campaign setup and maintenance can be compressed into a more consistent process without turning execution into an unexplained black box.
Finally, the system needs a memory and a multiplier.
Inspired by centralized winner-library concepts used in multi-agent advertising systems such as AdStellar AI, this combined role has two responsibilities.
The Winners Librarian maintains a centralized library of proven advertising elements, including:
Each element should be tagged with the context in which it was tested, including channel, audience, campaign objective, and observed results.
The Scaling Strategist uses that library to recommend the next opportunities.
It can suggest adapting a winning YouTube concept into Meta Reels, testing a successful offer in a new geography, or creating incremental variations around an established creative winner.
It should also account for creative fatigue and avoid assuming that an element will perform identically across every channel or audience.
Over time, these two roles become the system's institutional memory. They help prevent a familiar problem: great advertising ideas win, get forgotten, and are never systematically reused.
Taken together, this modular roster reflects the broader shift from composing software to composing intelligence described by MarTech.
You are no longer looking for one monolithic media-buying AI. You are building a bench of specialized agents that each perform a defined job and can be recomposed as platforms, formats, and business priorities evolve.
In a real ad-intelligence stack, orchestration is not an abstract multi-agent framework.
It is the minute-by-minute coordination of which agent moves first, what artifacts it produces, where those artifacts are stored, and which agent is allowed to touch advertising spend.
Think of it as an assembly line where every specialist has a defined task, but the handoffs and quality checks are consistent.
Let's walk through a practical spying-to-testing-to-scaling loop.
The loop usually begins with a competitive-intelligence agent.
It monitors competitor pages, public advertising libraries, reviews, and pricing changes, following the general approach described in MarTech's overview of AI agents for marketing workflows.
In orchestration terms, this agent has three responsibilities.
Normalize inputs. It collects available public information, such as ad creative, copy, landing-page content, and visible campaign details from sources such as Meta's Ad Library, TikTok Creative Center, Google Ads Transparency Center, and competitor websites.
It converts those observations into a common schema containing offer type, hook, creative format, funnel stage, audience clues, and observed metrics where available.
Write to the shared brain. Instead of sending disconnected reports or dumping files into folders, it updates a Competitive Intelligence collection in the unified source of truth.
Each entry is tagged by category, geography, funnel stage, source, and observation date.
Emit a trigger, not a decision. When a pattern reaches a defined threshold—for example, several competitors begin using similar UGC-style videos around the same customer problem—the agent raises an Opportunity Signal.
That signal becomes the handoff to the next agent. The research agent does not automatically build a campaign simply because it has detected a pattern.
This approach keeps the process structured and preserves the distinction between observing market activity and deciding what the business should do.
An experimentation planner listens for Opportunity Signals and translates promising observations into test briefs.
Here, orchestration requires a clear separation of responsibilities.
It designs tests, not launches. When it identifies a potentially useful pattern, it creates a structured Experiment Spec containing:
It aligns with business KPIs. The planner retrieves optimization goals from the governance layer rather than inventing them.
If a business prioritizes payback period and ROAS, those constraints should be included in the experiment specification from the beginning.
It reuses proven winners. When previous tests have produced useful results, the planner links to the corresponding assets in the Winners Library.
This reflects the value of centralized winner libraries, including concepts such as the Winners Hub discussed in relation to AdStellar's multi-agent advertising system.
At this stage, a human typically reviews the experiment specification and approves or edits it.
The team is not simply orchestrating prompts. It is orchestrating defined work products:
Opportunity Signals → Experiment Specs → Human Approval
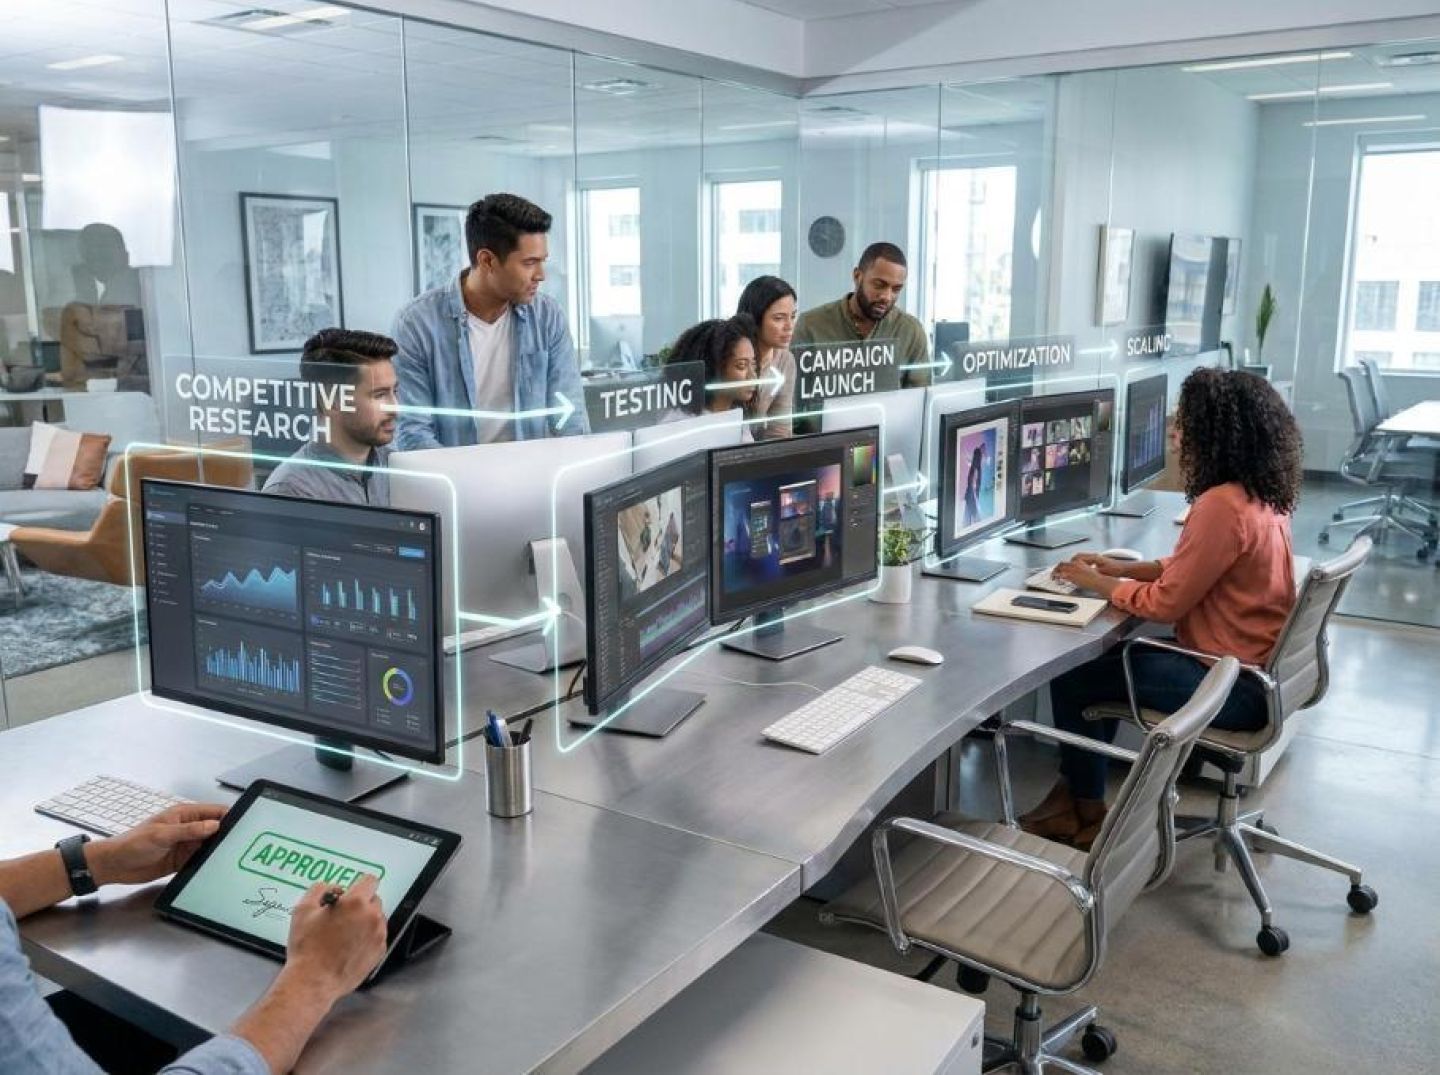
Once an experiment is approved, the campaign-builder agent takes over.
This is similar to the role of coordinated agents in systems such as AdStellar, which are designed to translate campaign instructions into advertising structures, as discussed in HubSpot's overview of campaign optimization platforms.
The launch process should follow three contracts.
Read-only on strategy, write-only on setup.
The agent consumes the approved Experiment Spec and the brand source of truth. It can configure campaigns, ad sets, and ads through authorized integrations.
It cannot independently change the experiment's KPI, strategic objective, or budget ceiling.
Platform-specific compilers.
Each advertising platform has different requirements, so the campaign builder needs a platform-specific configuration layer.
For example:
These platform-specific configurations should still follow the same underlying experiment specification.
Dry-run and diff.
Before publishing, the agent produces a Campaign Plan Diff showing what will be created, changed, or paused compared with the current account state.
A human or designated governance agent reviews the proposed changes.
Only after approval should the orchestration layer grant the campaign builder temporary write access to the relevant advertising account.
This creates an explicit checkpoint between planning and spending.
Once campaigns are live, the optimization agent and budget allocator become active.
The Optimization Agent ingests performance data and writes normalized Experiment Results back to the source of truth.
It can recommend:
However, these recommendations should initially take the form of documented suggestions and proposed changes, not silent in-place edits.
The Budget Allocator looks across active experiments and business-as-usual campaigns, then proposes spend adjustments within predefined boundaries.
Its recommendations should consider the performance objectives, budget limits, confidence thresholds, and risk rules defined in the governance layer.
When an experiment reaches its stop conditions, the system can recommend promoting a winner into an evergreen scaling portfolio, updating the Winners Library, and sending the latest results back to the experimentation planner.
The loop is now complete:
Spying informs testing. Testing produces evidence. Evidence informs scaling. Scaling creates the next round of intelligence.
Under the hood, the mechanics are deceptively simple: agents should not pass around loose, unstructured text as their primary handoff mechanism. They should pass defined artifacts.
Each artifact has an owner agent, a consumer agent, and an approval requirement where necessary.
That is what keeps the orchestra coordinated—and prevents agentic experimentation from quietly becoming unsupervised advertising spend.
If orchestration is the assembly line, trust is the factory's safety system.
Once you allow agents to research competitors, design experiments, launch campaigns, and influence scaling decisions, the question is no longer simply whether they can perform those tasks.
The more important question is whether you can demonstrate that they acted for the right reasons, using the right data, within the right boundaries.
This section is about maintaining control while automating aggressively through explicit guardrails, verifiable logs, and the ability to replace individual agents or models without rebuilding the entire workflow.
Most marketing organizations are still operating with limited or moderate levels of AI autonomy. Agents may perform tasks independently, but humans continue to direct, review, or approve important decisions.
That is a sensible approach for ad-intelligence power users.
You can aggressively automate execution while limiting where agents are allowed to act and what they can change.
In practice, this means separating permissions.
Read-only versus write versus spend permissions.
Your research and analysis agents should receive read-only access to public advertising information, analytics, and approved CRM data.
Your test-launcher agent can prepare drafts and propose budgets, but it should not automatically activate campaigns.
Only a tightly governed scaling agent—or an authorized human—should be able to commit spend within the approved limits.
Scope by objective and channel.
An agent might be allowed to launch and optimize low-budget creative tests on a specific channel while high-budget evergreen campaigns remain under human control.
As platforms roll out their own AI-powered campaign tools, treat them as constrained capabilities that your orchestration layer can use—not as unrestricted decision-makers with access to everything in your account.
You are not chasing maximum autonomy.
You are engineering bounded autonomy around the specific jobs you want automated.
A composable architecture offers an important advantage: each agent is a separate node in the system.
That means you can apply rules to individual agents without necessarily restricting the entire workflow.
There are three essential guardrail layers.
1. Policy guardrails
These define what must never happen.
Examples include:
Industry frameworks such as AAMP 2.3 are incorporating privacy controls, diligence requirements, and pricing safeguards for AI agents operating in advertising systems, as described in the IAB Tech Lab update covered by MarTech.
The same principle should apply internally: every agent that can access audiences, customer information, or advertising spend must operate within a policy layer that the organization controls.
2. Economic guardrails
These protect the business financially.
They can include:
Operational efficiency remains an important measure of AI success, as discussed in VideoWeek's coverage of IAB Europe research.
Economic guardrails help ensure that efficiency does not come at the expense of financial discipline.
3. Workflow guardrails
These define which agents can communicate with one another and which actions they can perform.
For example:
Think of these rules as API contracts between agents.
They do more than prevent mistakes. They make the overall system easier to understand, audit, and maintain.
Trust is not simply believing that an agent performs well today.
It is knowing that you can replace it tomorrow without rearchitecting your entire system.
This is where composability becomes especially valuable.
Organizations are moving beyond connecting SaaS applications and are beginning to compose intelligent capabilities—research agents, decision agents, and content agents—as reusable building blocks.
That is the broader direction described in MarTech's analysis of composable intelligence.
Treat each agent like a vendor in a portfolio.
Standardized interfaces.
Every agent that proposes creative tests should produce a consistent output structure, regardless of whether it uses a proprietary model or a third-party service.
For example, an experiment-planning agent should return a defined schema containing the hypothesis, channel, audience, creative variations, budget range, and KPIs.
Agnostic orchestration.
Your orchestrator should not depend on which copywriting or creative agent is being used.
It should depend on the interface the agent provides.
If the system can call a generate_variants function and receive properly tagged assets containing channel, hook, and audience information, the underlying provider can change without breaking the rest of the workflow.
Pluggable vendors and models.
If a specialized Meta campaign builder outperforms your internal campaign agent at bulk setup and rapid testing, you should be able to replace the existing component behind the same interface.
Platforms such as AdStellar demonstrate the direction of coordinated campaign-building capabilities, as discussed in the HubSpot Marketing Blog's review of campaign optimization tools.
The rest of your system should continue working because the data model, handoff contracts, and governance rules remain consistent.
Swappability is also a hedge against platform changes.
As TikTok, Reddit, and Meta introduce their own AI-powered assistants and campaign tools, the only reliable way to avoid platform lock-in is to keep your coordination logic and source of truth independent.
Platform agents should become tools your orchestrator can use—not the primary brain of your entire advertising operation.
Finally, trust requires an audit trail.
When an agent changes a bid, rotates a creative, or pauses an underperforming campaign, you should be able to answer three questions immediately:
A useful audit system should record:
Decision explanations should be understandable to the people responsible for reviewing them. A log that simply says an AI model decided to make a change is not sufficient.
The goal is to create a traceable chain from the original observation to the final outcome.
For example, if an optimization agent recommends pausing an advertisement, the record should show which KPI triggered the recommendation, what performance period was evaluated, whether the minimum sample-size requirement was met, and whether the action was automatically permitted or required approval.
This also makes debugging easier.
If an agent produces an incorrect recommendation, the team can identify whether the problem came from incomplete data, incorrect normalization, a flawed instruction, an outdated model, or an overly permissive rule.
A composable architecture is only as trustworthy as its ability to explain what happened.
Advertising platforms, AI models, and business priorities will continue to change.
A stack designed around one model, one platform, or one vendor may work initially, but it can become difficult to maintain as the environment evolves.
A more resilient architecture separates the components that should remain stable from those that are expected to change.
The shared data model, governance policies, artifact definitions, and approval process should provide the stable foundation.
Individual research agents, creative tools, campaign builders, and optimization models should remain replaceable.
That separation allows teams to experiment with new capabilities without disrupting the entire advertising operation.
The result is not just a collection of AI tools. It is an adaptable operating system for advertising intelligence.
The next stage of advertising intelligence will not be defined by how many AI tools a team uses.
It will be defined by how effectively those tools work together.
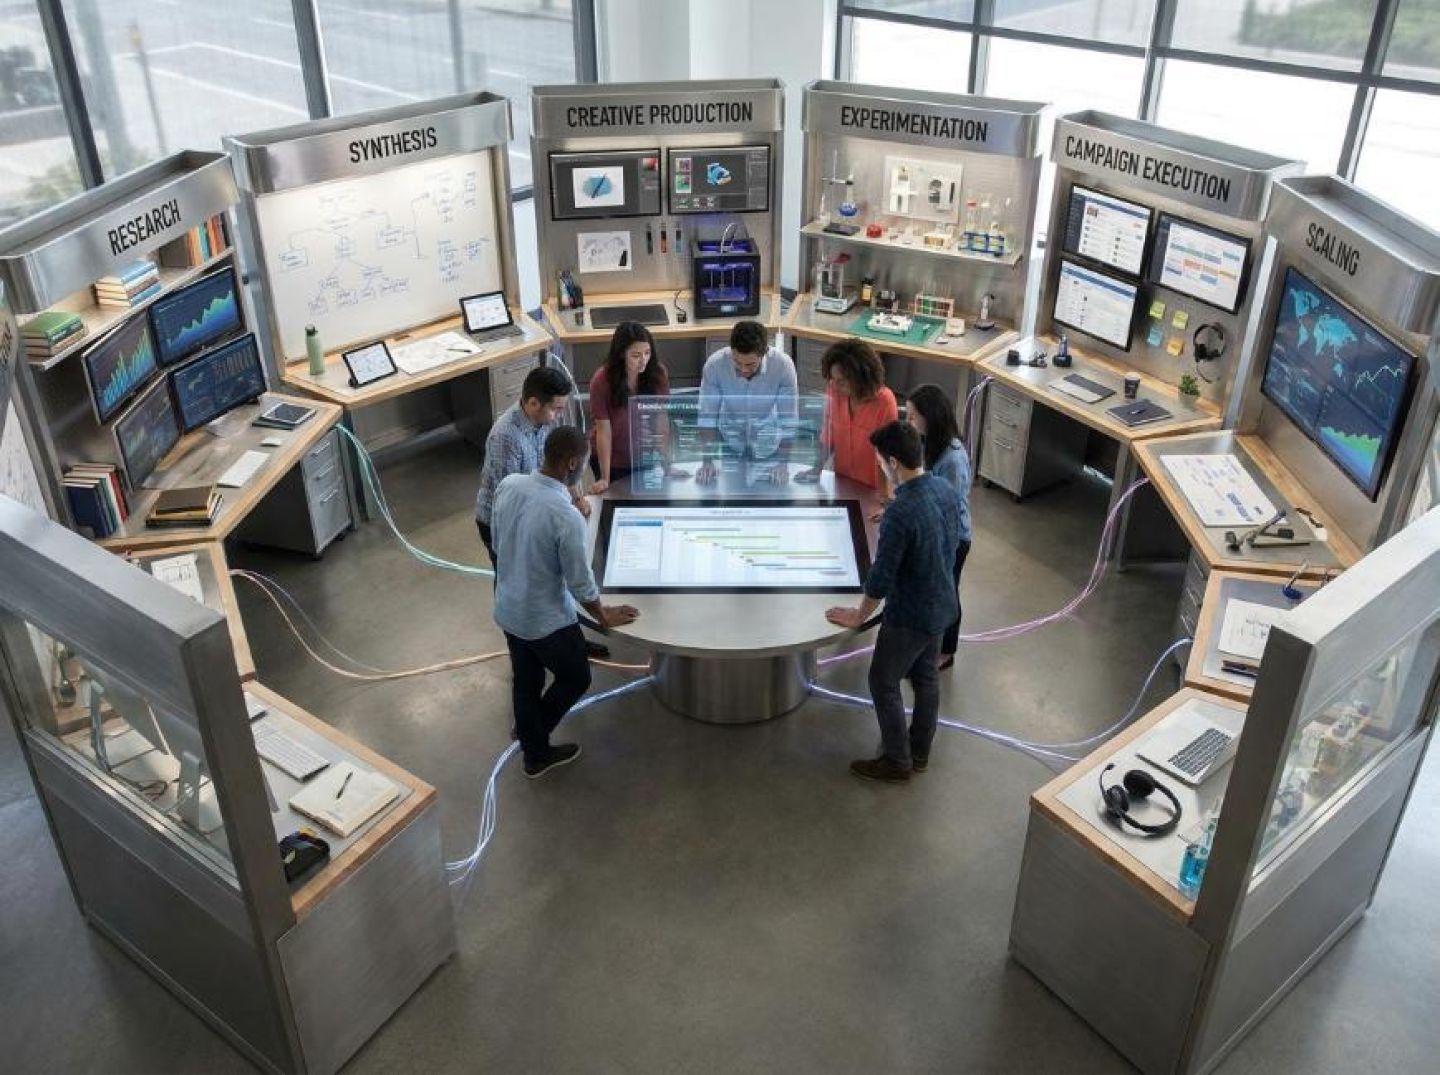
Competitive research, creative development, experimentation, campaign execution, and scaling are often treated as separate activities. A composable agent architecture connects them into one continuous operating loop.
A Cross-Network Spy Agent identifies market patterns. A Message and Offer Synthesizer turns those observations into hypotheses. A Creative Orchestrator prepares assets. An Experiment Designer structures the tests. A Campaign Launcher handles approved execution. And a Winners Librarian and Scaling Strategist preserve what works and identify the next opportunities.
But the agents alone are not the architecture.
The shared data backbone, governance layer, integration corridors, standardized handoffs, and audit trail are what make the system dependable.
For ad-intelligence power users, the opportunity is to move beyond collecting more competitor data or producing more creative variations. It is to build a system that consistently turns observations into structured experiments, experiments into evidence, and evidence into informed scaling decisions.
The objective is not to remove humans from advertising.
It is to remove unnecessary manual coordination so people can spend more time on strategy, judgment, and the decisions that genuinely require human oversight.
That is the promise of composable intelligence: a modular agent stack that can spy, test, and scale—while remaining transparent, governed, and adaptable as the advertising landscape changes.
Receive top converting landing pages in your inbox every week from us.
Featured
Discover how specialized AI agents can work together to monitor competitors, turn insights into experiments, launch campaigns, and scale winning strategies while keeping human oversight and governance in place.
David Kim
7 minNov 20, 2026
Quick Read
AI visibility is growing, but traditional analytics often fail to show its contribution to revenue. This framework connects AI discovery data with competitive ad intelligence, demand signals, assisted conversions, and offer-level revenue to help performance marketers measure whether AI-driven discovery is translating into business results.
Liam O’Connor
7 minNov 20, 2026
Most Read
Performance marketers don't need another prompt or disconnected AI tool. They need a coordinated system of agents that can monitor competitors, connect fragmented marketing data, test creative and funnel hypotheses, and surface better decisions. Explore how to move from prompt wrangling to commanding an intelligent performance marketing operation.
Priya Kapoor
7 minNov 19, 2026