12 minOctober 18, 2026

Our tools monitor millions of native, push, pop, and TikTok advertising campaigns.
Get StartedIn an AI-driven ad stack where agentic systems can generate hundreds of creatives and re-price bids in milliseconds, “good, fast, cheap” has quietly become table stakes. What performance teams actually need now is an operating system that makes their media buying visible, testable, and repeatable—a stable spine of orchestration that still holds its shape even as people, platforms, and algorithms swap in and out underneath it and autonomous agents keep turning the speed dial up.
“Good, fast, cheap” was built for a world where humans set the plan, platforms executed the plan, and optimizations happened on a human schedule. That world is gone. In an AI-first stack, media buying is no longer a linear workflow you push through a gantt chart; it’s a living system that reacts in milliseconds, mutates its own inputs, and floods you with more “optimization” than any team can meaningfully govern.
In that environment, “good, fast, cheap” doesn’t fail because it’s wrong. It fails because it’s too shallow. Cheap execution is now a default property of the tools, not a competitive advantage of the team.
Modern AdTech is already built around systems that can analyze streams of auction data, identify patterns, and make thousands of micro‑decisions in real time. As one overview of AI in AdTech explains, these engines don’t wait for your weekly performance review to act; they continuously tune bids, pricing, and audience selection across millions of impressions. Give them a ROAS target and they will happily re-price your auction strategy several times before lunch. Layer on generative and agentic tools that can turn one brief into hundreds of creative variants, and the marginal cost of “try another thing” collapses toward zero.
That collapse is exactly where the old operating mantra breaks. “Good” used to mean carefully crafted creative and a media plan you were proud to present. Today, an AI system can spin out “good‑enough” assets and placements at industrial scale. “Fast” used to mean getting a new campaign launched this week; now the platform can A/B, multivariate, and dynamically personalize in real time. “Cheap” used to be a hard‑won efficiency edge; today, as one analysis of AI experimentation in performance marketing points out, execution has become so inexpensive that the real risk is not overspending on tests, but drowning in them.
The result is a pattern nearly every scaled account exhibits: teams call winners on day two because the live dashboard curve looks friendly; they run tiny tests that could never meaningfully converge; they chase platform‑visible metrics the model can nudge while business‑visible metrics drift the wrong way; and, because starting something new is basically free, they rarely kill anything at all. AI doesn’t introduce these bad habits; it accelerates them. The clock speeds up, but the underlying governance doesn’t.
At the same time, AI is not arriving in a clean, unified channel. Each “smart” layer—bidder, agent, optimization engine—is another decision‑making hop in an already fragmented supply chain. As one programmatic leader put it, agentic AI is a “shiny new object,” but every additional buying path is also a new set of frictions and fees that classic supply‑path optimization then has to unwind. AI promises efficiency while quietly multiplying the number of places value can leak out of a buy.
This is why simply adding more AI into “good, fast, cheap” thinking is so dangerous. You’re not just making the same process faster; you’re introducing semi‑autonomous counterparts into your core operating system. As one perspective on AI guardrails in digital advertising argues, the winners will not be the companies that deploy AI the fastest, but those that can operate at machine speed while still maintaining human governance, visibility, and accountable control structures.
Complicating matters further, the ground under your channels is shifting while your stack is learning to walk. AI‑native search and assistants are siphoning off a meaningful share of informational queries, even as high‑intent commercial queries stay comparatively stable. An analysis of AI’s impact on traditional search shows informational search volume dropping while transactional search holds its value—which means the same spend pattern that worked last year may now be misaligned with how people actually discover and decide. In other words, the inputs to your AI systems are changing at the same time as the systems themselves.
Put all of this together and the flaw in “good, fast, cheap” becomes obvious. It optimizes for outputs—creative units launched, experiments run, CPCs lowered—while ignoring the properties that actually matter in an AI‑driven environment: whether you can see what the system is doing, whether you can reliably test what it claims works, and whether you can repeat success on purpose instead of by accident.
An AI‑era media operation that’s merely good, fast, and cheap will happily drive off a cliff—with beautiful creative, aggressive bids, and impeccable efficiency along the way. What it needs instead is an operating system designed for a world where machines move first and humans are accountable after. That operating system starts from a different standard: visible, testable, repeatable.
The starting point for a new operating system isn’t the media plan. It’s the brief itself.
Most organizations still brief like it’s 2012: one deck, one big idea, one flight, one end date. The orchestration is implied. “We’ll launch on these channels with this budget, then we’ll optimize.” That worked when campaigns were discrete events and platforms mostly did what you told them.
In an AI-first stack, that model collapses. Automated systems are no longer waiting for your next campaign; they are continuously reallocating budget, remixing creative, and shifting bids in the background. As omnichannel stacks sprawl across search, social, programmatic, retail media, and emerging surfaces like LLM inventory, the main problem is no longer “How do I make this one campaign better?” It’s “How do I see, govern, and evolve the whole system that’s already running?” As one analysis of omnichannel orchestration noted, the real value of AI now lies in coordinating complexity across channels, teams, and workflows, not just squeezing a few extra basis points out of individual placements through local optimization](https://www.adexchanger.com/co...).
That shift demands a different kind of brief. Instead of briefing a campaign, high-performing teams brief a visible system.
A visible system brief assumes that AI will be executing thousands of tiny decisions you’ll never personally touch. So it doesn’t just say what to launch; it defines how the system should behave over time and how you’ll observe and improve it. It’s closer to an operating manual than a launch memo.
Concretely, a visible system brief reframes four core elements.
1. From “target audience” to intent and states.
Traditional briefs lock onto static segments: age, income, interests. But modern targeting is drifting toward real‑time intent, where models respond to what a person is trying to do in that moment rather than who they are on paper. As one overview of AI‑native advertising put it, brands need to map messaging to decision stages and intent signals, not just fixed audience cohorts](https://martech.org/3-things-y...).
In a visible system brief, you define the behavioral states your media should detect (researching, comparing, ready to buy, churn‑risk, repeat buyer) and the observable signals that separate them across channels. That gives AI-driven bidding and creative systems a coherent map to follow, instead of a grab bag of personas that mean different things in every platform.
2. From “deliverables” to observable system outputs.
Legacy briefs obsess over assets: number of videos, variations of copy, formats per channel. In an AI landscape where spinning up new variations is nearly free, “deliverables” are a weak control surface. What matters is what the system produces in the wild: how often it explores new creative, how quickly it converges, how it reallocates spend, and how those patterns differ by intent state or channel.
A visible system brief explicitly lists the outputs you will monitor as first-class objects: exploration‑to‑exploitation ratios, test velocity, frequency curves, marginal CPA by experiment, saturation thresholds. This is what makes the system visible. You’re not waiting for a post‑campaign recap; you’re designing dashboards, logs, and decision points into the work from day one, much like an AI‑ready marketing OS that tracks requests, rules, and outcomes as part of an orchestrated life cycle](https://martech.org/the-7-laye...).
3. From “KPIs” to testable hypotheses.
Most briefs list KPIs as if they were inputs: “Our goal is a $60 CAC.” In reality, those are constraints, and AI will happily hit them in ways you don’t like—by chasing cheap, low‑quality conversions or starving top‑funnel learning.
In AI‑accelerated performance environments, teams are already discovering that volume and speed make traditional, loosely defined “tests” meaningless. They run tiny experiments, call winners in days, and end up drawing conclusions from noise rather than signal, as one analysis of scaled experimentation warned](https://www.searchenginejourna...).
A visible system brief encodes business logic as hypotheses, not wishes:
Each hypothesis includes: the mechanism you expect AI to exploit, the metrics that validate or falsify it, and the decision rule for what you’ll do next. That’s what makes the system testable: you know ahead of time what learning looks like and how it will change behavior.
4. From “campaign calendar” to repeatable operating loops.
Classic briefs are anchored in dates: launch, flight, blackout, wrap. In an environment where always‑on agents continuously experiment with creative, bids, and budget allocation, the more useful unit is the loop, not the flight.
A visible system brief defines the cadence of operations the way a product team would define sprints: daily anomaly checks, weekly hypothesis reviews, monthly re‑allocation decisions, quarterly structural refactors. It clarifies which signals are allowed to trigger automated changes and which require human judgment. That’s how you make media buying repeatable: not by locking in a plan, but by standardizing the loop that turns observations into new instructions for the system.
Redefining the brief this way doesn’t eliminate campaigns. It makes each campaign an instance of a longer‑lived, observable system—one that can be audited, tuned, and evolved as channels fragment, AI models shift, and consumer behavior moves under your feet. When your brief describes a visible system instead of a one‑off push, you finally have an operating spine sturdy enough to support “good, fast, cheap” execution without losing control of what the algorithms are actually doing on your behalf.
In a world where agentic bidding systems rewrite your plan every few minutes, “we’ll A/B it” is not an experimentation strategy. It’s a wish. Testable by design means you assume from the brief that the machine will move faster than your analysts — and you build a framework sturdy enough that speed doesn’t turn every result into fiction.
The first shift is architectural: experiments become the default state of the system, not special projects. When AI media platforms can spin up hundreds of variants and optimize in real time, the bottleneck is no longer execution; it’s whether you can still trust the learning. As one overview of AI-native advertising notes, speed is now a competitive advantage because brands can test “hundreds of variations quickly” and adapt in days, not quarters, raising the premium on tight strategy and upstream clarity about what’s being tested and why (MarTech).
That calls for three non‑negotiables baked into every campaign: a testable hypothesis, a guardrailed environment, and a promotion path from experiment to “always‑on” that doesn’t collapse under volume.
A testable hypothesis sounds basic, but in AI‑era media buying it has to be more precise. “Lower CPA” is not a hypothesis; it’s an aspiration. “In high‑intent search, conversational ad copy that mirrors natural language queries will drive a 15% higher lead‑to‑opportunity rate than control at constant spend” is something you can design a system around. It forces you to declare the mechanism (conversational language), the arena (high‑intent search), the business metric (lead‑to‑opportunity), and the acceptable tradeoffs.
This is especially critical as user behavior shifts. With conversational AI handling more informational queries and traditional search holding steady for commercial intent, as one PPC analysis found, the real opportunity is in capturing that stable, transactional demand rather than chasing mid‑funnel noise (Real FiG Advertising & Marketing). Your hypotheses should acknowledge this landscape: you’re not just testing ads; you’re testing how your system captures intent that’s fragmenting across search engines, AI assistants, and walled gardens.
Once you know what you’re testing, you need guardrails that separate learning from live‑ammo chaos. In practice, that means two operational tracks: a frontier track for bounded experiments and a fast‑follow track where only proven patterns graduate into scaled automation. This mirrors the broader AI advice to keep experimentation and production distinct, using controlled pilots with human oversight before plugging anything into core workflows, a distinction one industry analysis framed as essential to keeping AI systems governable as they grow more powerful (AdExchanger).
In media terms, your frontier track might be 5–15% of budget behind explicit tests: new bid strategies, fresh audience signals, different creative frameworks, novel channels. Each runs with pre‑declared success thresholds, minimum sample sizes, and — crucially — a sunset date. If a test can’t hit significance within the allotted impression or conversion budget, it doesn’t belong in the backlog; it belongs in the graveyard.
The fast‑follow track is where AI earns its keep. Once a pattern consistently clears your frontier thresholds — say, a particular message framework that drives incremental revenue, not just clicks — you let the machine operationalize it at scale. Here, orchestration matters more than automation. You’re not simply “turning on” winning settings; you’re connecting them into your broader operating system so that targets, budgets, creative rules, and measurement plans stay coherent with your overall strategy, echoing what an AI‑ready marketing OS is meant to do from intake to learning loop (MarTech).
The final piece of “testable by design” is survivability under speed: rules that stay intact when the number of concurrent experiments 10x. That means standardizing a few things you used to improvise:
When you treat experiments as a permanent layer of the operating system instead of sporadic projects, AI becomes an accelerant for learning instead of a fog machine. The stack stays fast, but results stay believable — not because machines got smarter, but because you designed the work to be testable before a single impression went live.
If “testable” is the brain of this operating system, “repeatable” is the muscle. You cannot run AI‑era media at scale if every campaign starts from a blank doc, every analyst invents their own naming convention, and every optimization lives in someone’s head. Repeatable workflows give you a way to move at machine speed without turning your operation into an un-auditable blur.
The building blocks are simple: standardized prompts, durable handoff docs, and living playbooks. The execution is not.
In an autonomous, agentic environment, prompts are the new media briefs. They’re how you talk to the engines that actually do the work — LLM copilots that translate strategy into cross‑channel plans, and bidding agents that negotiate auctions in milliseconds. As AI moves from task automation to orchestrating full campaign life cycles, the way you brief these systems becomes a strategic asset.
Most teams today treat prompts like rough notes: ad hoc, personal, lost in Slack. That’s fine for experimentation; it’s a liability in production. As AI becomes a “strategic partner” in planning and decision‑making, the prompts that work need to be versioned, documented, and shared, the way you would treat actual code, not clever one‑offs hidden in someone’s browser history, as described in coverage of how AI is reshaping omnichannel orchestration.
A standardized prompt library for media buying should include:
Each template is tested, renamed with a clear convention, tagged by use case and channel, and stored where everyone can see and improve it. Over time, this becomes the interface between your human judgment and increasingly autonomous AI systems, the kind of “governable” control surface that AI‑driven advertising urgently needs, as argued in calls for clear operational guardrails in digital advertising.
The second component is the humble handoff document — upgraded for an AI‑first workflow.
In a rule‑based world, most of the orchestration lived in people’s heads. Planners “just knew” what the buyer meant. Analysts “just knew” which lookback window to use. In an AI‑driven, omnichannel stack where optimization, reporting, and reconciliation span disconnected systems, that implicit glue doesn’t scale.
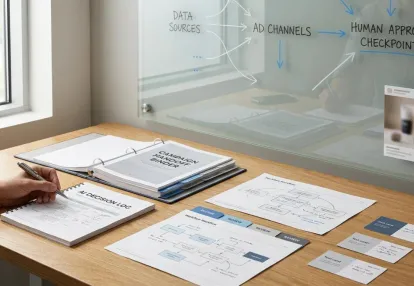
You need a single canonical artifact that travels with the work from brief to build to optimization to post‑mortem. In practice, that means a tightly structured document (or workspace) that captures:
When AI systems increasingly “analyze data, identify patterns, and make real‑time decisions” in what some have called an emerging agentic ad economy, this artifact gives you traceability. You can answer, “What was this system trying to do? Under which constraints? Against which definition of success?” without reconstructing intent from scattered emails.
Handoff docs also make your experimentation framework portable. An incrementality test design created for paid search can, with minimal edits, be reused for retail media or CTV. That reuse is where compounding efficiency lives.
Prompts and handoff docs describe the work; playbooks describe how to think.
In the pre‑AI era, a playbook was often just a checklist. Today, it has to encode decision logic that survives speed and complexity. You’re no longer telling a buyer “if ROAS > X, increase bids.” You’re giving an LLM‑driven planner and a portfolio of bidding agents a set of conditional rules for how to explore, exploit, and shut down lines of effort across the whole funnel.
A robust AI‑era playbook:
This is also where you adapt to macro shifts in behavior. As access to conversational AI tools reduces low‑intent informational queries while leaving transactional intent comparatively stable, a smart playbook reallocates effort away from questions that ChatGPT now answers and toward high‑intent, commercially oriented searches. That shift shouldn’t be reinvented account by account; it should roll out as a standard operating change, expressed in prompts, handoff docs, and test templates.
Crucially, playbooks must be versioned and auditable. When an experiment framework changes — new thresholds, different attribution logic, updated channel mix — you don’t quietly overwrite the old rules. You cut a new version, record the rationale, and link it from the prompts and handoff docs that depend on it. This is how you avoid the trap of “frontier experimentation” leaking into core production without a control architecture, a failure mode that industry observers have warned against.
Put together, standardized prompts, durable handoff docs, and versioned playbooks are how you turn media buying from a series of clever one‑offs into an operating system. They make your best work visible, portable, and improvable — so every new campaign starts where the last one left off, and every new AI agent plugs into a way of working that’s already designed to be visible, testable, and repeatable.
Most teams are trying to do two incompatible things with one operating motion: learn what’s possible with AI and hit this quarter’s number. That’s how a “fun new agent test” on Tuesday becomes an unexplained 30% budget swing by Friday.
The answer is not to move slower. It’s to split your operating system into two distinct tracks: a frontier track for experiments and a fast‑follow production track for scaled deployment.
On the frontier side, your goal is learning, not efficiency. This is where you trial agentic bid strategies, LLM‑generated creative, answer‑engine SEO, or new optimization goals. Think of it as a bounded sandbox: limited budgets, constrained surfaces, and explicit kill switches. As one industry leader argued, the danger isn’t using AI, it’s letting “frontier experimentation” leak straight into core workflows without sufficient control architecture.
Frontier work has its own rules of engagement:
Crucially, the output of frontier isn’t a “shiny new toy,” it’s a promotion packet: documented behavior, known failure modes, and the minimum viable playbook that would let a normal team run it without drama. That documentation is what qualifies an idea to enter your second track.
The fast‑follow production track is built for repeatability and governance. It’s where you take patterns that worked in the lab and wire them into standardized briefs, handoff docs, and playbooks. Instead of campaign teams improvising their own AI tactics, you encode what you learned from frontier as reusable workflows: when to use an agent, what inputs it needs, what naming conventions and tags to apply, how to read its reporting.
This is also where orchestration matters more than raw optimization. As omnichannel complexity explodes, the biggest value of AI isn’t eking out a few extra basis points on bids; it’s coordinating planning, activation, and optimization across fragmented systems so humans stop living in spreadsheets, as one analysis of omnichannel orchestration argued. The fast‑follow track is your orchestration layer: clear intake, defined guardrails, automated handoffs, and a visible audit trail from decision to outcome.
Two things keep the tracks connected instead of becoming silos:
When you operate in two tracks, you resolve the central tension of AI‑era media buying. You can push the frontier hard—new agents, new surfaces, new signals—without betting the quarter on unproven systems. And you can run production at machine speed—high‑frequency optimizations, omnichannel orchestration—without losing visibility or control. Frontier defines what’s possible; fast‑follow makes it repeatable, governable, and safe to scale.
Tags
Receive top converting landing pages in your inbox every week from us.
Quick Read
Discover how AI watermarks, disclosure labels, and Content Credentials are changing competitive advertising intelligence. Learn how to build a responsible ad spy stack that identifies AI-generated creatives, evaluates competitor strategies ethically, protects brand trust, and supports transparent, bias-aware advertising decisions.
Rachel Thompson
7 minOct 20, 2026
In-Depth
Learn how to build AI advertising handoff documentation that keeps automated media buying transparent, accountable, and ready for audits. Discover how to standardize campaign strategy, AI governance, competitive intelligence, experiment tracking, prompt logs, and compliance safeguards across advertising channels.
David Kim
7 minOct 20, 2026
Recently Updated
Discover how competitive ad intelligence and creative performance data can help marketers build AI-powered advertising systems that stand out from generic, AI-generated content. Learn how to use Anstrex to identify proven creative patterns, develop a reusable creative genome, and combine data-driven optimization with distinctive human creativity to build campaigns that convert.
Marcus Chen
7 minOct 19, 2026